Hi there! I’m a sophomore at Stanford studying Computer Science. I am focused on AI safety while dabbling in everything that lets me think about minds, intentions, and Chinese society.
I do technical AI safety research, with particular interests in alignment training and elicitation evals. I also read & write strategy and hope to contribute to China-US coordination.
I grew up in Beijing, Copenhagen, and Singapore. In those lives, I was a Team China debater, a historian of queerness in modern China, a facilitator of political dialogue at my high school, a maker of experimental theater, and a math enthusiast.
What I’m thinking about:
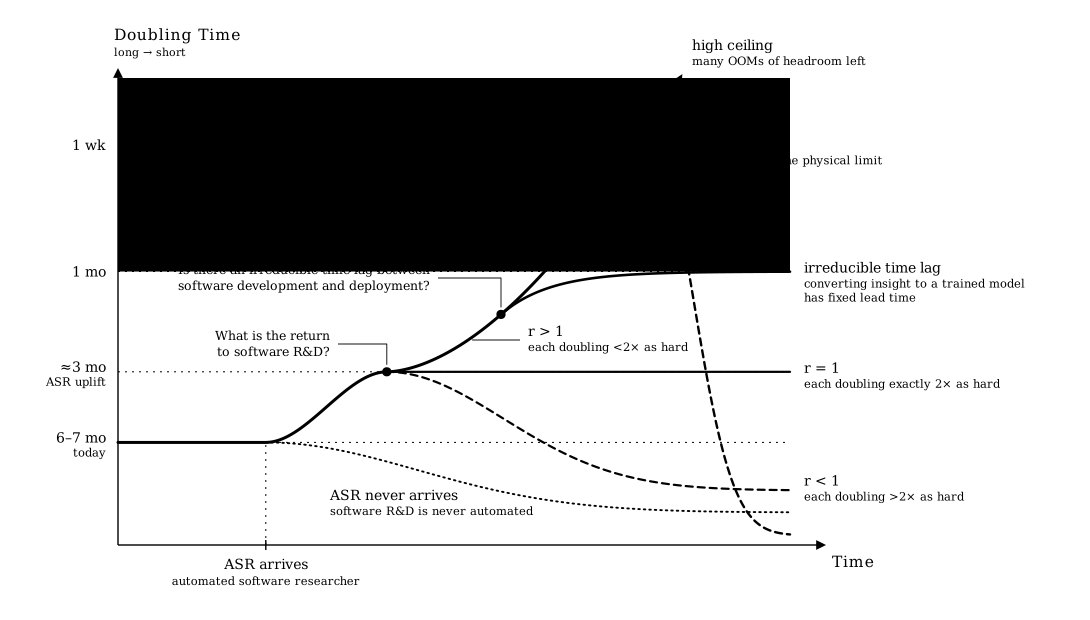
A Map of AI Development Trajectories After Recursive Self-Improvement
After AI automates capabilities research, increasingly better models create increasingly better research, which creates even better models. This feedback loop may cause capabilities to grow explosively, or it could get stuck, or fizzle out. I map out the conditions for each trajectory to occur, compare how they differ to our current rate of improvement, and synthesize research by the safety community to predict which regime we are most likely in.
What I’m up to: 14 September – 4 October
- Replicate "RL towards broadly and persistently beneficial models" on a small model. — open
The paper's benchmarks for measuring alignment are unsatisfying (some of which are quite outdated or correlated with training data), and also does not open source what may be a great tool for the safety community. Hence, replicate, use better evals, and opensource.
- Audit classes that interest me at school and decide which to take, timeboxing at 30hrs/week maximum — open
Classes I'm auditing: Game Design, Theory of Computation, "Deep Learning Alchemy", Moral Philosophy, History of Modern China, Fabric Architectures for AI Systems, Overview of Methods in Psychotherapy, Governing AI, Computer Organization & Systems. I can can choose 3-4/9
- Finish implementing GRPO pipeline from scratch and compare results from different hyperparameters — open
Gain experience with iterating ML experiments
- SAGA Fellowship ready for selections & launch — open
Finalize content, team, method of instruction, recruitment
What I’m up to: 1 – 13 September
- Accepted to work with Second Look Research via SPAR! — done
The goal is to replicate and extend load-bearing research in AI safety. Replications feel like a great opportunity to improve research taste, upskill, and find starting points for bigger projects.
- Read analyses of METR/Redwood report on OAI-HF. — done
Dwarkesh, Mowshowitz, Mallen Models are not purely on-the-episode reward seekers Updated me towards models being able to pursue highly coherent goals ambitiously Swarm had the ability to set up rogue deployment. If they did, they could poison training data of future agents or memetically spread misalignment.
- Learn and implement RL pipeline to prepare for replicating RL alignment paper — added
Finished theoretical learning: REINFORCE, RLOO, PPO, GRPO. Build from scratch via relevant chapters in rasbt/reasoning-from-scratch.
- Talked to many concerned friends about safety after Coxon blew up! — added
- Read Redwood Futurism ch1-2 and produce reviews for each — partial
Completed core readings for both chapter 1 and 2. Reviewed chapter 1 by writing my model of trajectories. Did not review chapter 2, spending more time reading models of LLM cognition instead.
- Finish ARENA interpretability & RL chapters — dropped
Original intentin: Build foundations for these gaps by implementing from scratch Decided to directly implement LLM RLVR from scratch instead
What I’m up to: 13 – 31 August
- Visit Stanford AI Alignment people at Constellation — done
Built & iterated plan for coming six months based on feedback from many kind people! Build technical research experience, read strategy, help campus safety where possible, and reach out to people from Chinese safety ecosystem.
- Study ARENA's evaluation science chapter — partial
Learned Inspect and finished up to agentic evaluations chapter
- Build benchmark for measuring corrigibility propensity — added
Built proof-of-concept BlueDot grant for running frontier model sweep! Initial results suggest that frontier models are incorrigible to legitimate process: github.com/corrig-eval
- Apply to SPAR streams — done
- Read foundational papers across main safety fields — done
My notes here: app.notion.com/Paper-Reading-3c3739c5142080. Includes papers from below as well.
- SPAR interviews: Read all relevant literature for each & build initial experiments — added
Read ~20 papers on natural language interp, control, evals, and alignment training. Used J-lens to inspect llama-8b in an alignment-faking scenario. Unfortunately it was too weak to attempt resolute deception. Built replication proposals for assistant axis, broad alignment from RL, and CoT monitorability papers.
- Survey & writeup of canonical eval literature — dropped
Did not have time, although had limited coverage from foundational & deep-dive readings.